01 — The two apps
Two apps. Pick a setup.
One is the simple agent — LibreChat, the open-source ChatGPT-style app: everyone logs in with their own account, conversations stay private, MCP web search, on your box. It chats and searches; it doesn’t read your email. The other is the agent team — OpenMausBot: a roster of bots, each with its own model, its own computer, its own jobs, working 24/7. Both open source. Both on your machine.
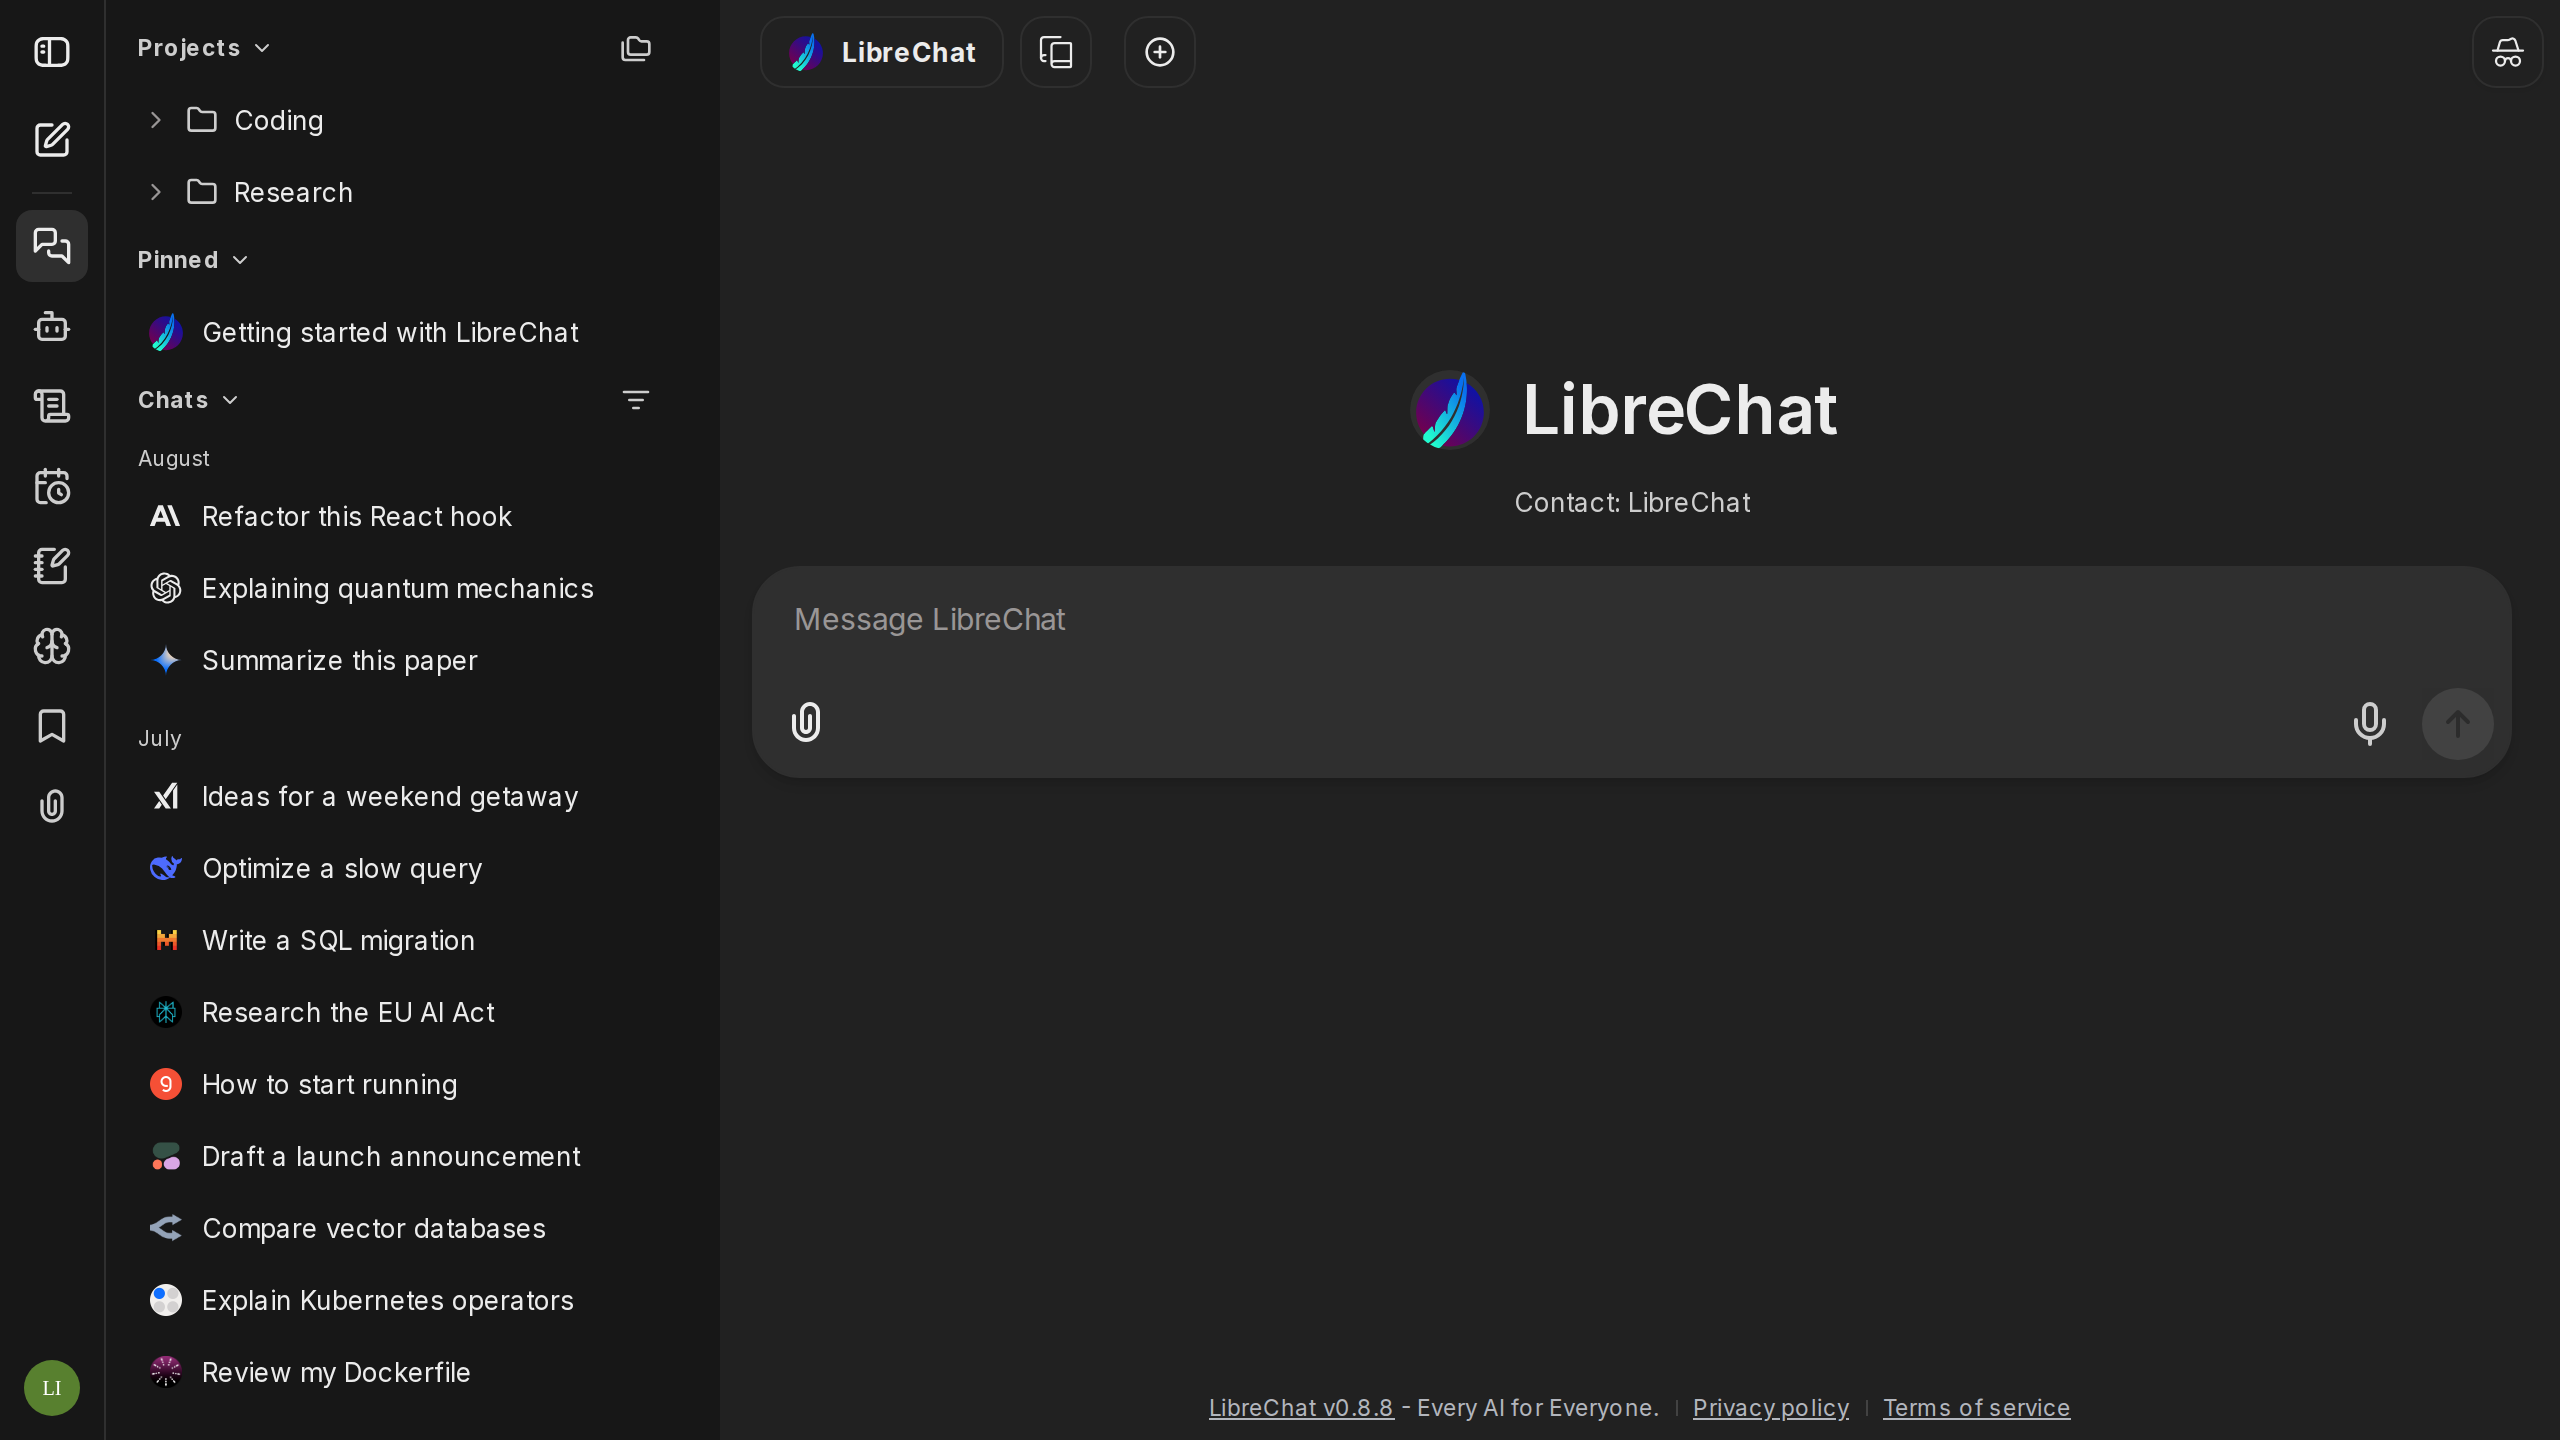
LibreChat — the simple agent
Open source · 46.9k GitHub stars. On your install it runs local models via llama.cpp, with MCP search wired in. Everyone logs in with their own account — chats stay private, all on your network.
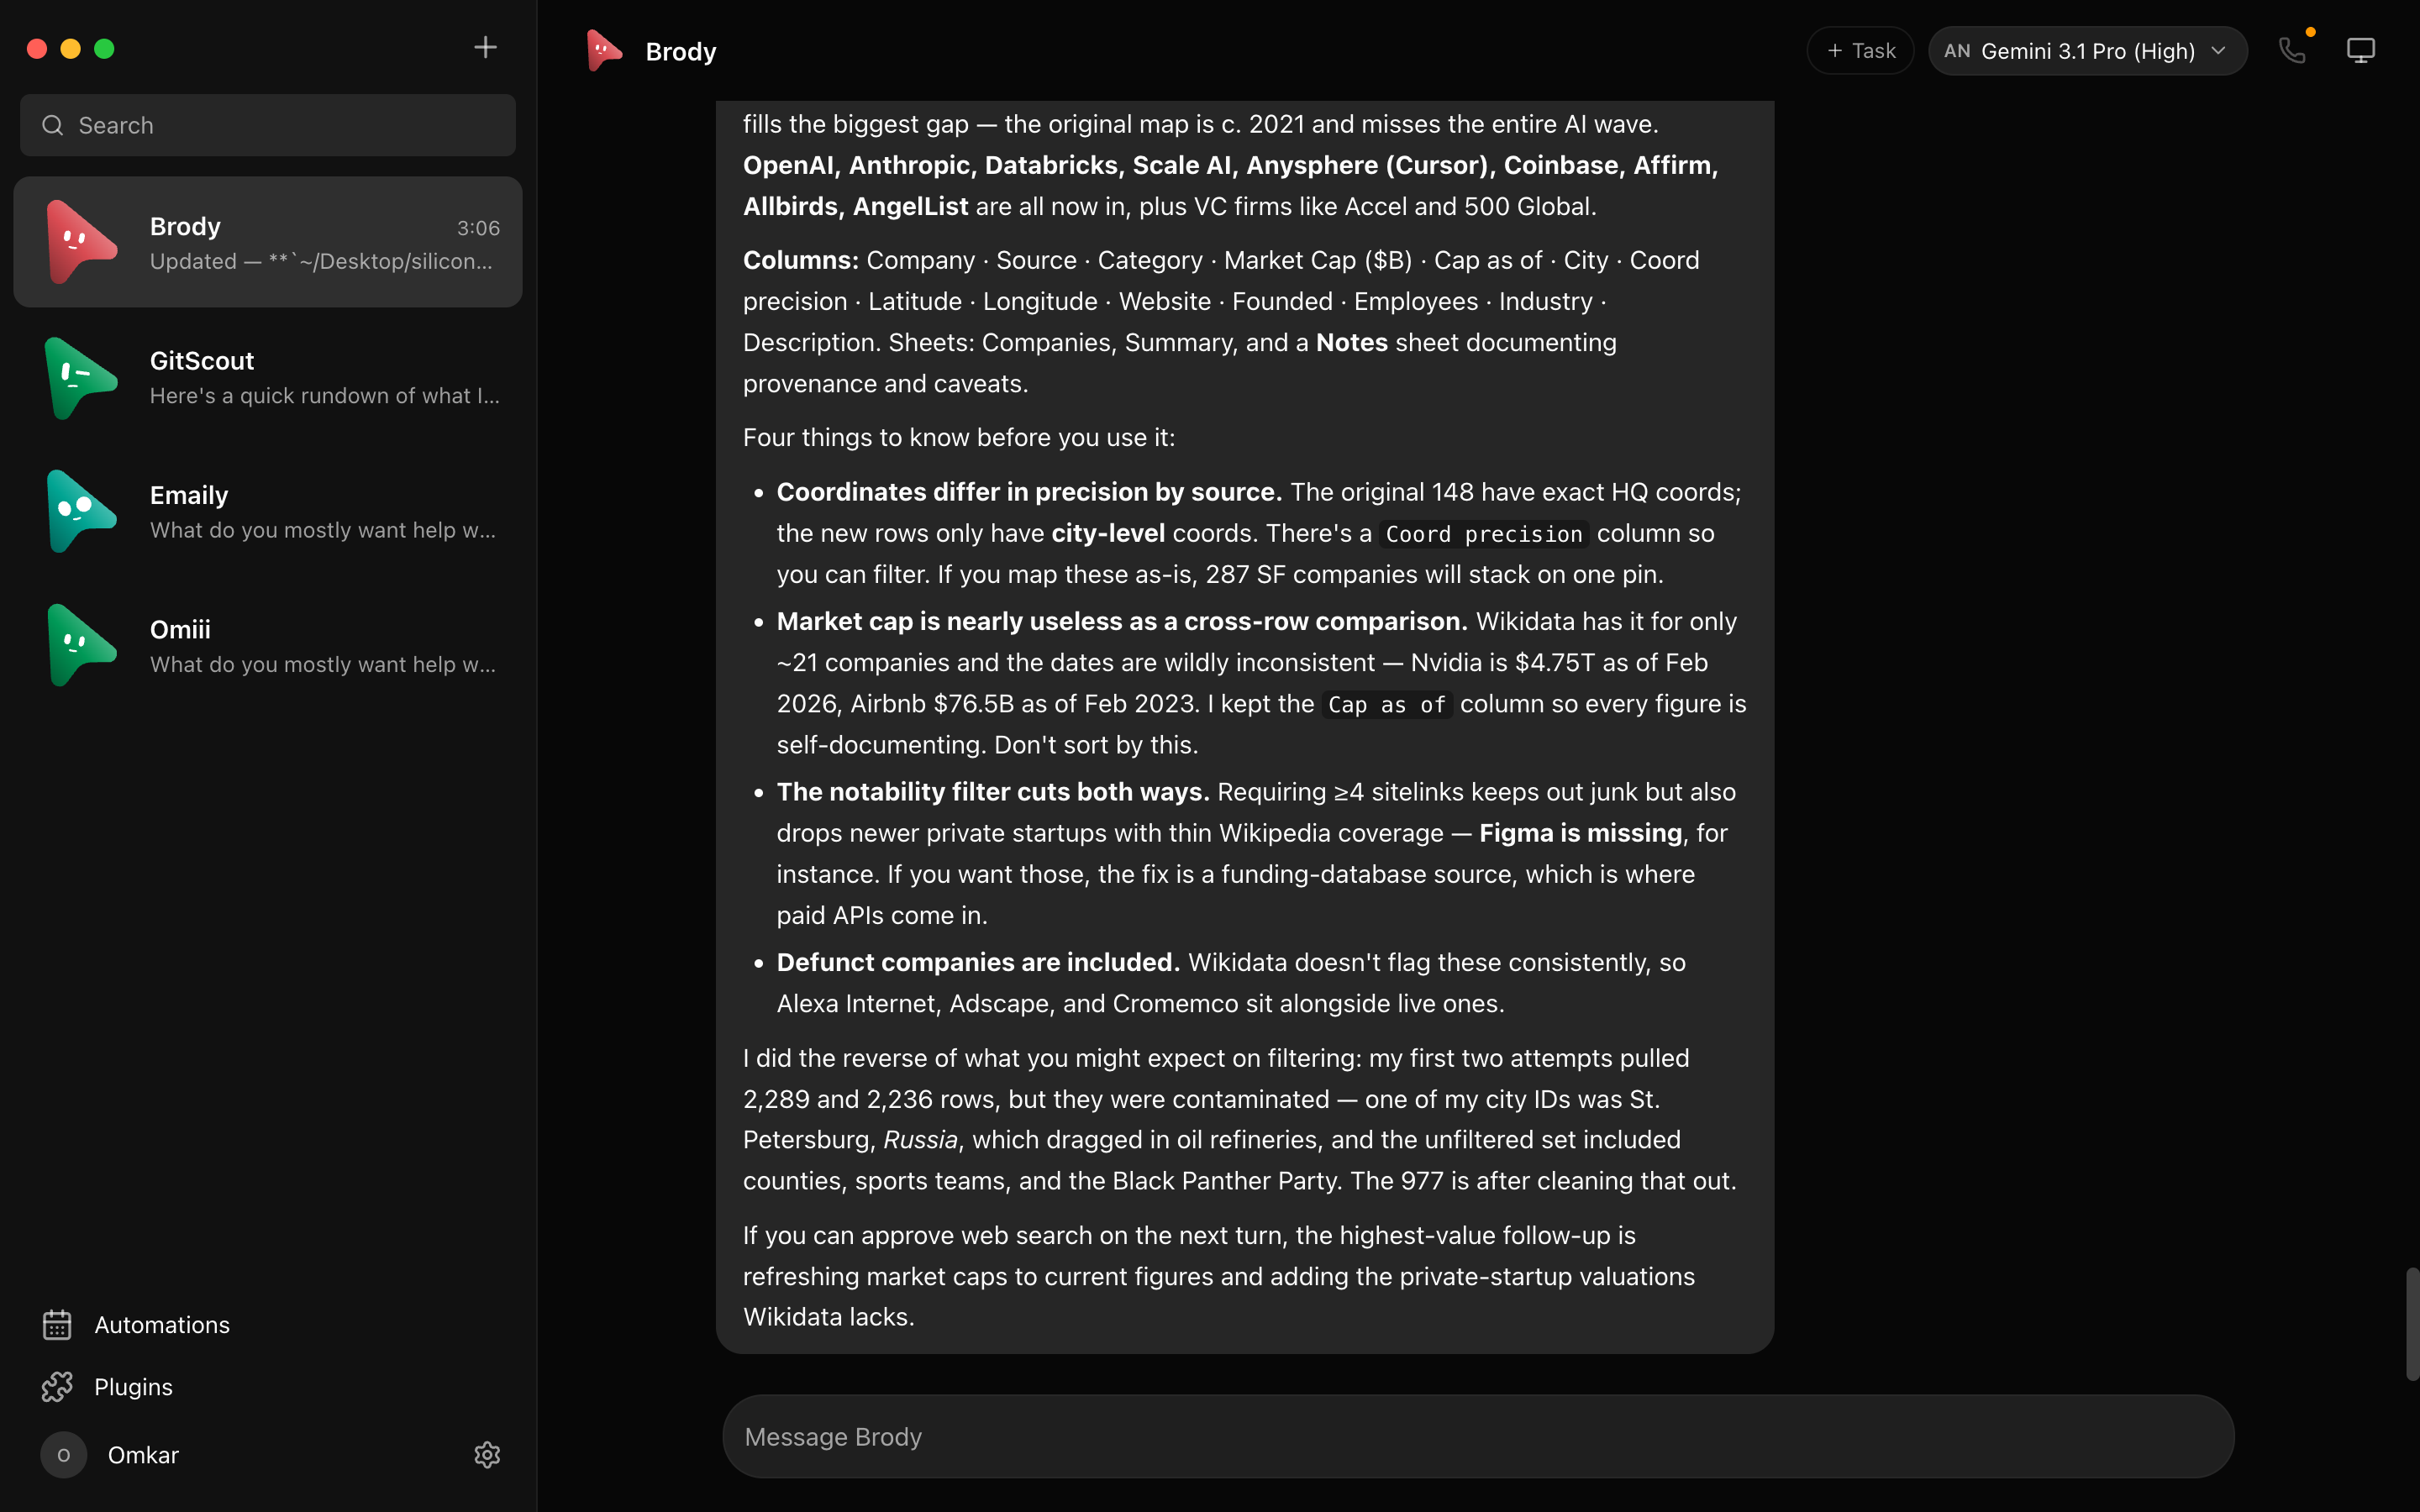
OpenMausBot — the agent team
Open source · Apache 2.0. Every contact is a real agent — its own model, computer and apps. Reads email, uses a desktop, runs routines 24/7.
The free LibreChat demo runs on their cloud — sign in with Google, Discord, or GitHub, no card. Trusted by NASA, Visa, Harvard, Stanford. On your install, both apps run on your box.
02 — The brain
Not a small model. A real one.
The standard brain we install is Qwen3.8 27B — the thinker. Here it is next to the other brains we install, and the cloud ceiling. Each has a job.
| benchmark | Qwen3.8 27B the thinker · on your machine |
Muse Glimmer 30B the all-rounder · local |
GPT-OSS 20B the fast one · local |
GPT-5.5 the ceiling · their cloud |
|---|---|---|---|---|
| Agentic work | 62.6 | 75.5* | 24.6 | 59.2 |
| OSWorld — real computer tasks | 84.3% | 65.9% | 62.6% | 78.7% |
| SWE-bench Pro — real code fixes | 61.7% | 51.2% | 37.1% | 58.6% |
| SWE-bench Verified | 86.0% | 76.0% | 60.7% | 82.6% |
| LiveCodeBench | 84.0% | — | — | 85.3% |
| MMLU-Pro — knowledge | 84.3% | — | 72.5% | 88.1% |
| Cost per million tokens | $0 — it’s yours | $0 — it’s yours | $0 — it’s yours | $5 in / $30 out |
Each brain has a job: Qwen3.8 is the thinker — deep agent work, code, multi-step. Muse Glimmer is the all-rounder — strong general agent work, reads images, runs on a 24 GB card. GPT-OSS is the fast one — snappy, tool-savvy, on modest boxes. GPT-5.5 is the ceiling — the cloud frontier, when you want it. Public scores, November 2026 (BenchLM + each model’s published card; * = MCP-Atlas, Meta’s agentic benchmark; some GPT-OSS figures are estimated). Different harnesses — read the shape, not the decimals. And every local brain stays at $0 per token, forever.
Now book the real one.
The free demo is the UI on their cloud. Your install is the same apps, on your box, with the local brain behind them.